Monitoring the status of clusters
Dashboard, Grafana, alerts - a single overview.
Where to see the status
1. Cluster dashboard (main source)
Where: Select a cluster in the left menu - a dashboard of the expanded cluster will open. When creating a client cluster: Cluster → Client Clusters → cluster name; until deployment is completed, the Dashboard page in the Administration section, only the Cluster tab is available. More details: Cluster Dashboard.
Screenshot: dashboard of a deployed cluster
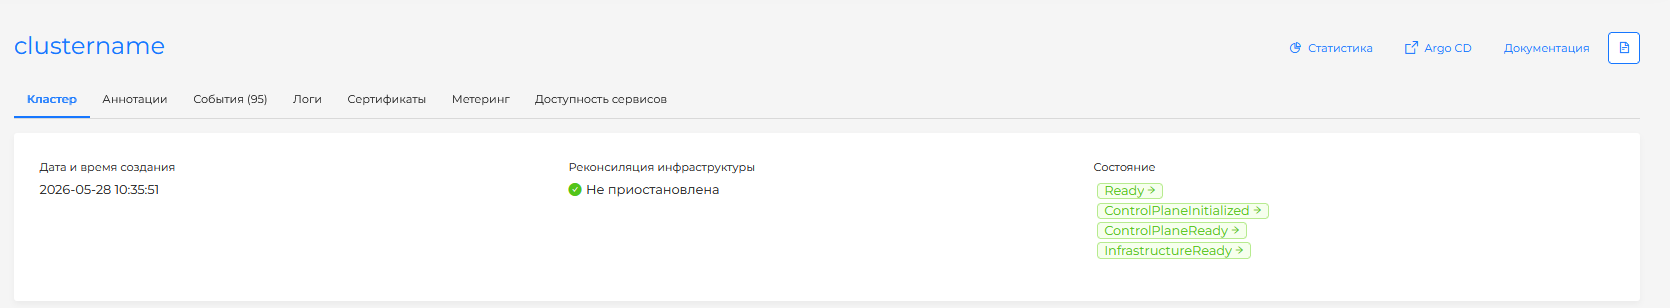
Dashboard tabs (after deployment is complete):
| Tab | What displays |
|---|---|
| Cluster | Node groups (Ready/NotReady, pods), description (Kubernetes version, status, subnets, provider, advanced security settings), update, service counters, triggered alerts (with metrics collection enabled) |
| Annotations | List of cluster annotations (monitoring_id, tag, color coding, etc.) |
| Events | Cluster object events: date and time, source, object, type, text |
| Logs | Collected logs (with shturval-log-collector enabled and shturval-metrics-collector running in the management cluster) |
| Certificates | Cluster Certificate Validity |
| Metering | Resource consumption by namespace (CPU/hour, RAM/hour) |
| Availability of services | Availability cards for key services (with shturval-metrics-collector enabled in the cluster and shturval-monitoring in the management cluster) |
2. “Statistics” button (Grafana)
Where: On the cluster dashboard there is the Statistics button.
What it gives: Transition to Grafana with cluster metrics (CPU, memory, network, pods, etcd, API server, etc.). Requires shturval-metrics-collector (in the cluster) and shturval-dashboards, shturval-monitoring (in the management cluster) to be enabled.
Grafana direct URL: https://dashboards.<cluster-domain> (for example, dashboards.clustername.ip-10-11-12-13.shturval.link).
More details: Pre-installed dashboards, How to add your own dashboard to Grafana.
3. “Alerts” section
Where: In the side menu of the platform - Alerts → View alerts.
What it displays: Alerts based on metrics and logs (Firing, Pending, Inactive). Grouped by rule groups.
Settings: For delivery to Email, Telegram, Webhook, recipients and routes are configured. See How to set up alerting.
4. Sections “Nodes”, “Services and repositories”
Nodes: List of cluster nodes with filtering by role (Control Plane, Worker).
Services and repositories: Installed services (shturval-backup, shturval-log-collector, shturval-dashboards, etc.). Status of each service (Auto, Off, Patched).
Daily control (short checklist)
It is recommended to check once a day (or when receiving alerts):
| No. | Check | Where to watch |
|---|---|---|
| 1 | All nodes are in Ready status | Cluster dashboard → Cluster tab (“Node groups” block), or Nodes section |
| 2 | No Pods in CrashLoopBackOff | Workloads → Pods, filter by status |
| 3 | No critical alerts | Alerts → View Alerts, Firing tab |
| 4 | CPU/RAM usage is normal | Grafana (Statistics button) or Compute Resources dashboard |
| 5 | Clusters in Ready status | Clusters → list |
Time: 5-15 minutes if there are multiple clusters.
Setting up alerting for automatic control
To avoid checking manually, set up alerts:
- Alerts → Recipients - add Email, Telegram or Webhook.
- Alerts → Routes — set up delivery to recipients.
- Alert rules - predefined rules are already there. If necessary, add custom ones (for example, for disk usage > 80%).
More details: How to set up alerting based on metrics, How to set up alerting based on logs.
Additional
- Pre-installed dashboards - overview of dashboards Kubernetes, Services, VictoriaMetrics, etc.
- How to add your own dashboard to Grafana - provisioning via ConfigMap
- Monitoring architecture